加载社区管道和组件
[[open-in-colab]]
社区管道
请参阅 GitHub Issue [#841](https://github.com/huggingface/diffusers/issues/841),了解我们为什么添加社区管道,以帮助每个人轻松分享他们的工作而不被拖慢。
社区管道是指任何与原始论文实现不同的 [DiffusionPipeline] 类(例如,[StableDiffusionControlNetPipeline] 对应于 Text-to-Image Generation with ControlNet Conditioning 论文)。它们提供了额外的功能或扩展了管道的原始实现。
有许多很酷的社区管道,例如 Marigold Depth Estimation 或 InstantID,你可以在这里找到所有官方的社区管道 here。
社区管道有两种类型,一种存储在 Hugging Face Hub 上,另一种存储在 Diffusers GitHub 仓库中。Hub 管道是完全可定制的(调度器、模型、管道代码等),而 Diffusers GitHub 管道仅限于自定义管道代码。
| GitHub community pipeline | HF Hub community pipeline | |
|---|---|---|
| usage | same | same |
| review process | open a Pull Request on GitHub and undergo a review process from the Diffusers team before merging; may be slower | upload directly to a Hub repository without any review; this is the fastest workflow |
| visibility | included in the official Diffusers repository and documentation | included on your HF Hub profile and relies on your own usage/promotion to gain visibility |
从本地文件加载
社区管道也可以从本地文件加载,只要你传递一个文件路径。传递的目录路径必须包含一个 pipeline.py 文件,该文件中包含管道类。
py
pipeline = DiffusionPipeline.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5",
    custom_pipeline="./path/to/pipeline_directory/",
    clip_model=clip_model,
    feature_extractor=feature_extractor,
    use_safetensors=True,
)
从特定版本加载
默认情况下,社区管道从 Diffusers 的最新稳定版本加载。要从其他版本加载社区管道,请使用 custom_revision 参数。
使用 from_pipe 加载
社区管道也可以使用 [~DiffusionPipeline.from_pipe] 方法加载,这允许你在不增加额外内存开销的情况下加载和重用多个管道(更多内容请参阅 重用管道 指南)。内存需求由加载的最大单个管道决定。
例如,让我们从一个 Stable Diffusion 管道加载一个支持 长提示加权 的社区管道。
py
import torch
from diffusers import DiffusionPipeline

pipe_sd = DiffusionPipeline.from_pretrained("emilianJR/CyberRealistic_V3", torch_dtype=torch.float16)
pipe_sd.to("cuda")
# load long prompt weighting pipeline
pipe_lpw = DiffusionPipeline.from_pipe(
    pipe_sd,
    custom_pipeline="lpw_stable_diffusion",
).to("cuda")

prompt = "cat, hiding in the leaves, ((rain)), zazie rainyday, beautiful eyes, macro shot, colorful details, natural lighting, amazing composition, subsurface scattering, amazing textures, filmic, soft light, ultra-detailed eyes, intricate details, detailed texture, light source contrast, dramatic shadows, cinematic light, depth of field, film grain, noise, dark background, hyperrealistic dslr film still, dim volumetric cinematic lighting"
neg_prompt = "(deformed iris, deformed pupils, semi-realistic, cgi, 3d, render, sketch, cartoon, drawing, anime, mutated hands and fingers:1.4), (deformed, distorted, disfigured:1.3), poorly drawn, bad anatomy, wrong anatomy, extra limb, missing limb, floating limbs, disconnected limbs, mutation, mutated, ugly, disgusting, amputation"
generator = torch.Generator(device="cpu").manual_seed(20)
out_lpw = pipe_lpw(
    prompt,
    negative_prompt=neg_prompt,
    width=512,
    height=512,
    max_embeddings_multiples=3,
    num_inference_steps=50,
    generator=generator,
    ).images[0]
out_lpw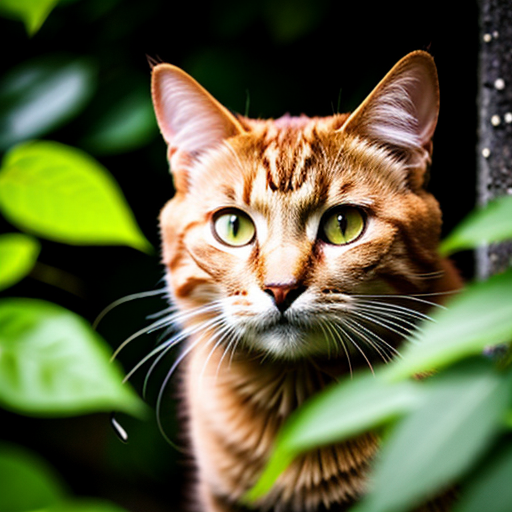
示例社区管道
社区管道是一种非常有趣和富有创意的方式,可以为原始管道添加新的和独特的功能。你可以在 diffusers/examples/community 文件夹中找到所有社区管道,其中包含如何使用它们的推理和训练示例。
本节展示了几个社区管道,希望它们能激发你创建自己的管道(欢迎提交 PR 以添加你的社区管道,并通知我们进行审查)!
TIP
[~DiffusionPipeline.from_pipe] 方法特别适用于加载社区管道,因为许多社区管道没有预训练权重,而是在现有管道(如 Stable Diffusion 或 Stable Diffusion XL)的基础上添加了功能。你可以在 使用 from_pipe 加载 部分了解有关 [~DiffusionPipeline.from_pipe] 方法的更多信息。
社区组件
社区组件允许用户构建可能包含 Diffusers 不支持的自定义组件的管道。如果你的管道包含 Diffusers 尚不支持的自定义组件,你需要提供这些组件的实现作为 Python 模块。这些自定义组件可能是 VAE、UNet 和调度器。在大多数情况下,文本编码器是从 Transformers 库中导入的。管道代码本身也可以进行自定义。
本节展示了用户如何使用社区组件来构建社区管道。
你将使用 showlab/show-1-base 管道检查点作为示例。
- 从 Transformers 导入并加载文本编码器:
python
from transformers import T5Tokenizer, T5EncoderModel

pipe_id = "showlab/show-1-base"
tokenizer = T5Tokenizer.from_pretrained(pipe_id, subfolder="tokenizer")
text_encoder = T5EncoderModel.from_pretrained(pipe_id, subfolder="text_encoder")- 加载调度器:
python
from diffusers import DPMSolverMultistepScheduler

scheduler = DPMSolverMultistepScheduler.from_pretrained(pipe_id, subfolder="scheduler")- 加载图像处理器:
python
from transformers import CLIPImageProcessor

feature_extractor = CLIPImageProcessor.from_pretrained(pipe_id, subfolder="feature_extractor")
现在你将加载一个 自定义 UNet,在本例中,已经为你方便地在 showone_unet_3d_condition.py 中实现了。你会注意到类名从 [
UNet3DConditionModel] 改为ShowOneUNet3DConditionModel,因为 [UNet3DConditionModel] 已经存在于 Diffusers 中。ShowOneUNet3DConditionModel类所需的所有组件都应放在 showone_unet_3d_condition.py 中。完成这些后,你可以初始化 UNet:
python
    from showone_unet_3d_condition import ShowOneUNet3DConditionModel

    unet = ShowOneUNet3DConditionModel.from_pretrained(pipe_id, subfolder="unet")
    ```

5. 最后,你将加载自定义管道代码。在这个示例中,代码已经为你创建好了,位于 [pipeline_t2v_base_pixel.py](https://huggingface.co/sayakpaul/show-1-base-with-code/blob/main/pipeline_t2v_base_pixel.py)。该脚本包含一个自定义的 `TextToVideoIFPipeline` 类,用于从文本生成视频。与自定义 UNet 一样,自定义管道所需的所有代码都应放在 `pipeline_t2v_base_pixel.py` 中。

一旦所有内容都准备就绪,你可以使用 `ShowOneUNet3DConditionModel` 初始化 `TextToVideoIFPipeline`:

```python
from pipeline_t2v_base_pixel import TextToVideoIFPipeline
import torch

pipeline = TextToVideoIFPipeline(
    unet=unet,
    text_encoder=text_encoder,
    tokenizer=tokenizer,
    scheduler=scheduler,
    feature_extractor=feature_extractor
)
pipeline = pipeline.to(device="cuda")
pipeline.torch_dtype = torch.float16
将管道推送到 Hub 以与社区分享!
python
pipeline.push_to_hub("custom-t2v-pipeline")在成功推送管道后,你需要进行以下几项更改:
- 将 model_index.json 中的
_class_name属性更改为"pipeline_t2v_base_pixel"和"TextToVideoIFPipeline"。 - 将
showone_unet_3d_condition.py上传到 unet 子文件夹。 - 将
pipeline_t2v_base_pixel.py上传到管道 仓库。
为了运行推理,初始化管道时添加 trust_remote_code 参数以处理所有后台的"魔法"。
WARNING
作为使用 trust_remote_code=True 的额外预防措施,我们强烈建议你在 [~DiffusionPipeline.from_pretrained] 中通过 revision 参数传递一个提交哈希,以确保代码没有被更新为包含恶意的新代码行(除非你完全信任模型所有者)。
python
from diffusers import DiffusionPipeline
import torch

pipeline = DiffusionPipeline.from_pretrained(
    "<change-username>/<change-id>", trust_remote_code=True, torch_dtype=torch.float16
).to("cuda")

prompt = "hello"

# Text embeds
prompt_embeds, negative_embeds = pipeline.encode_prompt(prompt)

# Keyframes generation (8x64x40, 2fps)
video_frames = pipeline(
    prompt_embeds=prompt_embeds,
    negative_prompt_embeds=negative_embeds,
    num_frames=8,
    height=40,
    width=64,
    num_inference_steps=2,
    guidance_scale=9.0,
    output_type="pt"
).frames
作为额外的参考,可以查看 stabilityai/japanese-stable-diffusion-xl 仓库的结构,该仓库也使用了 trust_remote_code 功能。
python
from diffusers import DiffusionPipeline
import torch

pipeline = DiffusionPipeline.from_pretrained(
    "stabilityai/japanese-stable-diffusion-xl", trust_remote_code=True
)
pipeline.to("cuda")